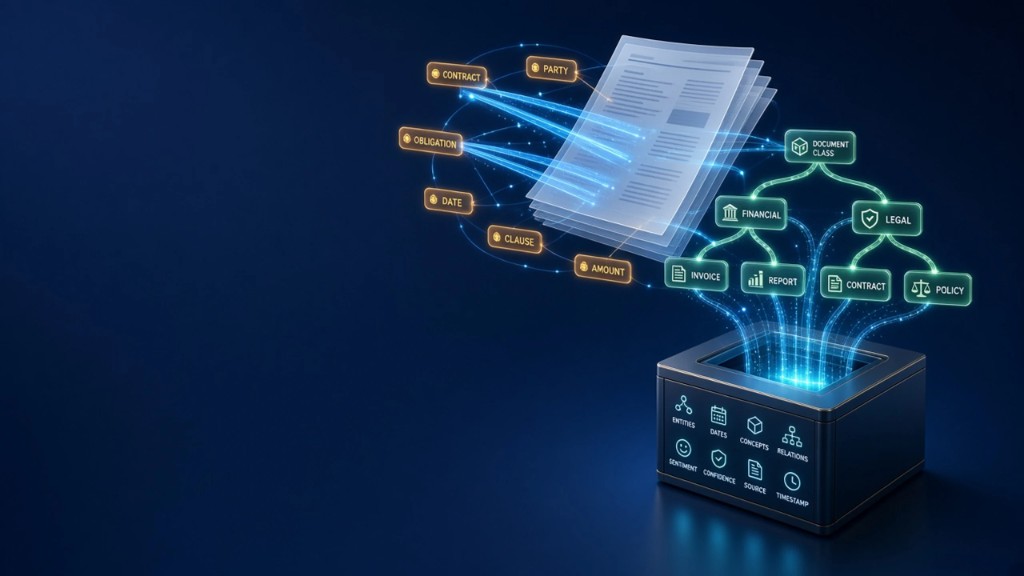
AI Metadata Enrichment Engine
Multi-agent pipeline using Llama 3.3 70B and FAISS to enrich digital asset metadata at scale, with a Streamlit review interface for human approval.
01 Challenge
Digital asset libraries need consistent, accurate metadata to support search, rights management, and downstream distribution. Manual metadata tagging at scale is time-consuming, inconsistent, and limits the effectiveness of DAM systems.
02 Solution
DesIDEA built an AI Metadata Enrichment Engine using a LangGraph-orchestrated multi-agent pipeline. Llama 3.3 70B analyzes digital assets and generates enriched metadata; FAISS vector search provides contextual retrieval from the existing asset library and taxonomy; a Streamlit interface lets content teams review, approve, and refine AI-generated metadata before it is committed to the DAM system.
Multi-agent pipeline
LangGraph coordinates enrichment steps end to end.
Llama 3.3 70B
Generates enriched metadata from digital assets.
FAISS context
Vector search aligns tags with existing taxonomy.
Human review
Streamlit workflow before any DAM commit.
03 Approach
- Automate metadata generation while keeping humans in the approval loop
- Use vector search so new tags stay consistent with the existing taxonomy
- Orchestrate agents with LangGraph for inspectable enrichment steps
- Commit to DAM only after review so quality and rights stay protected
Technologies: LangGraph, Llama 3.3 70B, FAISS, Streamlit, multi-agent pipeline, vector search.
04 Impact
- Automated metadata generation across large asset libraries
- Human review workflow ensuring metadata quality before DAM commit
- Consistent taxonomy application using vector-search-based contextual matching